PG Phriday: Burnt TOAST
A financial firm hired me in 2010 to revise their Postgres cluster architecture. During my stint there, I learned a healthy respect for their event_log table. But perhaps “respect” is the wrong word here, as it was more of a deep loathing. This table, you see, was the canonical ledger of system events and consisted of several million rows.
The high row count wasn’t a problem by itself. We kept a tight visibility window and archived frequently. Unfortunately for us, one of the columns was an unconstrained TEXT type that commonly held a large blob of XML. Thus any fetch from this table was inordinately slow. Writing was equally painful. We went through great pains to shape the application itself to avoid touching it except when absolutely necessary. It was evil incarnate.
The performance of this table initially confused and enraged me—until I remembered about TOAST. Postgres likes to innocuously dub this backronym “The Oversized-Attribute Storage Technique” but DBAs in the field maintain a love/hate relationship with the system. Whether that’s justified is a different question.
On the surface, it’s a way to store huge blocks of data elsewhere to keep tuples small and avoid exceeding the relatively petite 8KB data page size. Postgres creates a shadow table for the bulky content, splits it up into chunks, and stores a pointer in the original row. It’s an elegant solution to a pressing issue, but there are deep performance implications.
So let’s dig into precisely why DBAs secretly dread large text-based columns, shall we?
Getting TOASTy
To really understand what happened in my event_log case, it’s good to reconstruct some semblance of it.
CREATE TABLE event_log
(
  event_id       BIGINT GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  ticker         VARCHAR(4) NOT NULL,
  strike         INT NOT NULL,
  shares         INT NOT NULL,
  event_data     JSON NOT NULL -- Ours was XML, but modern times...
  --- More columns went here
);
And then we can bootstrap the table with 100k rows. Just enough to make it annoying! The data column needs to be big, but not absolutely gigantic. Let’s start with up to 1000 data points:
INSERT INTO event_log (ticker, strike, shares, event_data)
SELECT left(md5((a.id % 100)::TEXT), 4), a.id % 100, a.id % 100 * 10,
       (SELECT jsonb_object_agg('field_' || f, random(1, 1000))
          FROM generate_series(1, id % 1000 + 1 ) f)
  FROM generate_series(1, 100000) a (id);
Great! Now where did all of that data go? If you thought, “Into the event_log table of course!” you’re wrong. Instead, Postgres helpfully created a TOAST table for most of it. Let’s check the pg_class catalog for the other objects:
SELECT c.relname, t.relname AS toast_table, i.relname AS toast_index
  FROM pg_class c
  JOIN pg_class t ON t.oid = c.reltoastrelid
  JOIN pg_index x ON x.indrelid = t.oid
  JOIN pg_class i ON i.oid = x.indexrelid
 WHERE c.relname = 'event_log';

  relname  |  toast_table   |     toast_index
-----------+----------------+----------------------
 event_log | pg_toast_16401 | pg_toast_16401_index
That’s three objects for the price of one: the original table, a toast table, and a toast table index. This doesn’t always happen, but if your table has a text-like column without a maximum length, it probably did. In this case, it’s because an unbounded JSON column can contain anything, so Postgres preemptively initialized a TOAST table to store the “anything”.
What goes in is a bit more subtle, and is where the trouble starts brewing.
Compounded Butter
There’s a kind of inherent hierarchy that determines how data gets managed. The typstorage column in the pg_type catalog explains how this works for each type Postgres understands. There are four valid storage methods:
PLAIN (p): The value stays inline and uncompressed. This is the default for fixed-width types like INT and TIMESTAMPTZ.
MAIN (m): Compression is allowed, with TOAST only as the last resort. The default for NUMERIC.
EXTERNAL (e): TOAST is allowed, but compression is not.
EXTENDED (x): Anything is fair game. This is the default for TEXT, BYTEA, JSONB, and most other variable-length types.
Postgres imposes a loop on all text-based column types in a tuple that it applies until the entire row is under the standard 8KB page threshold (minus overhead). It looks something like this:
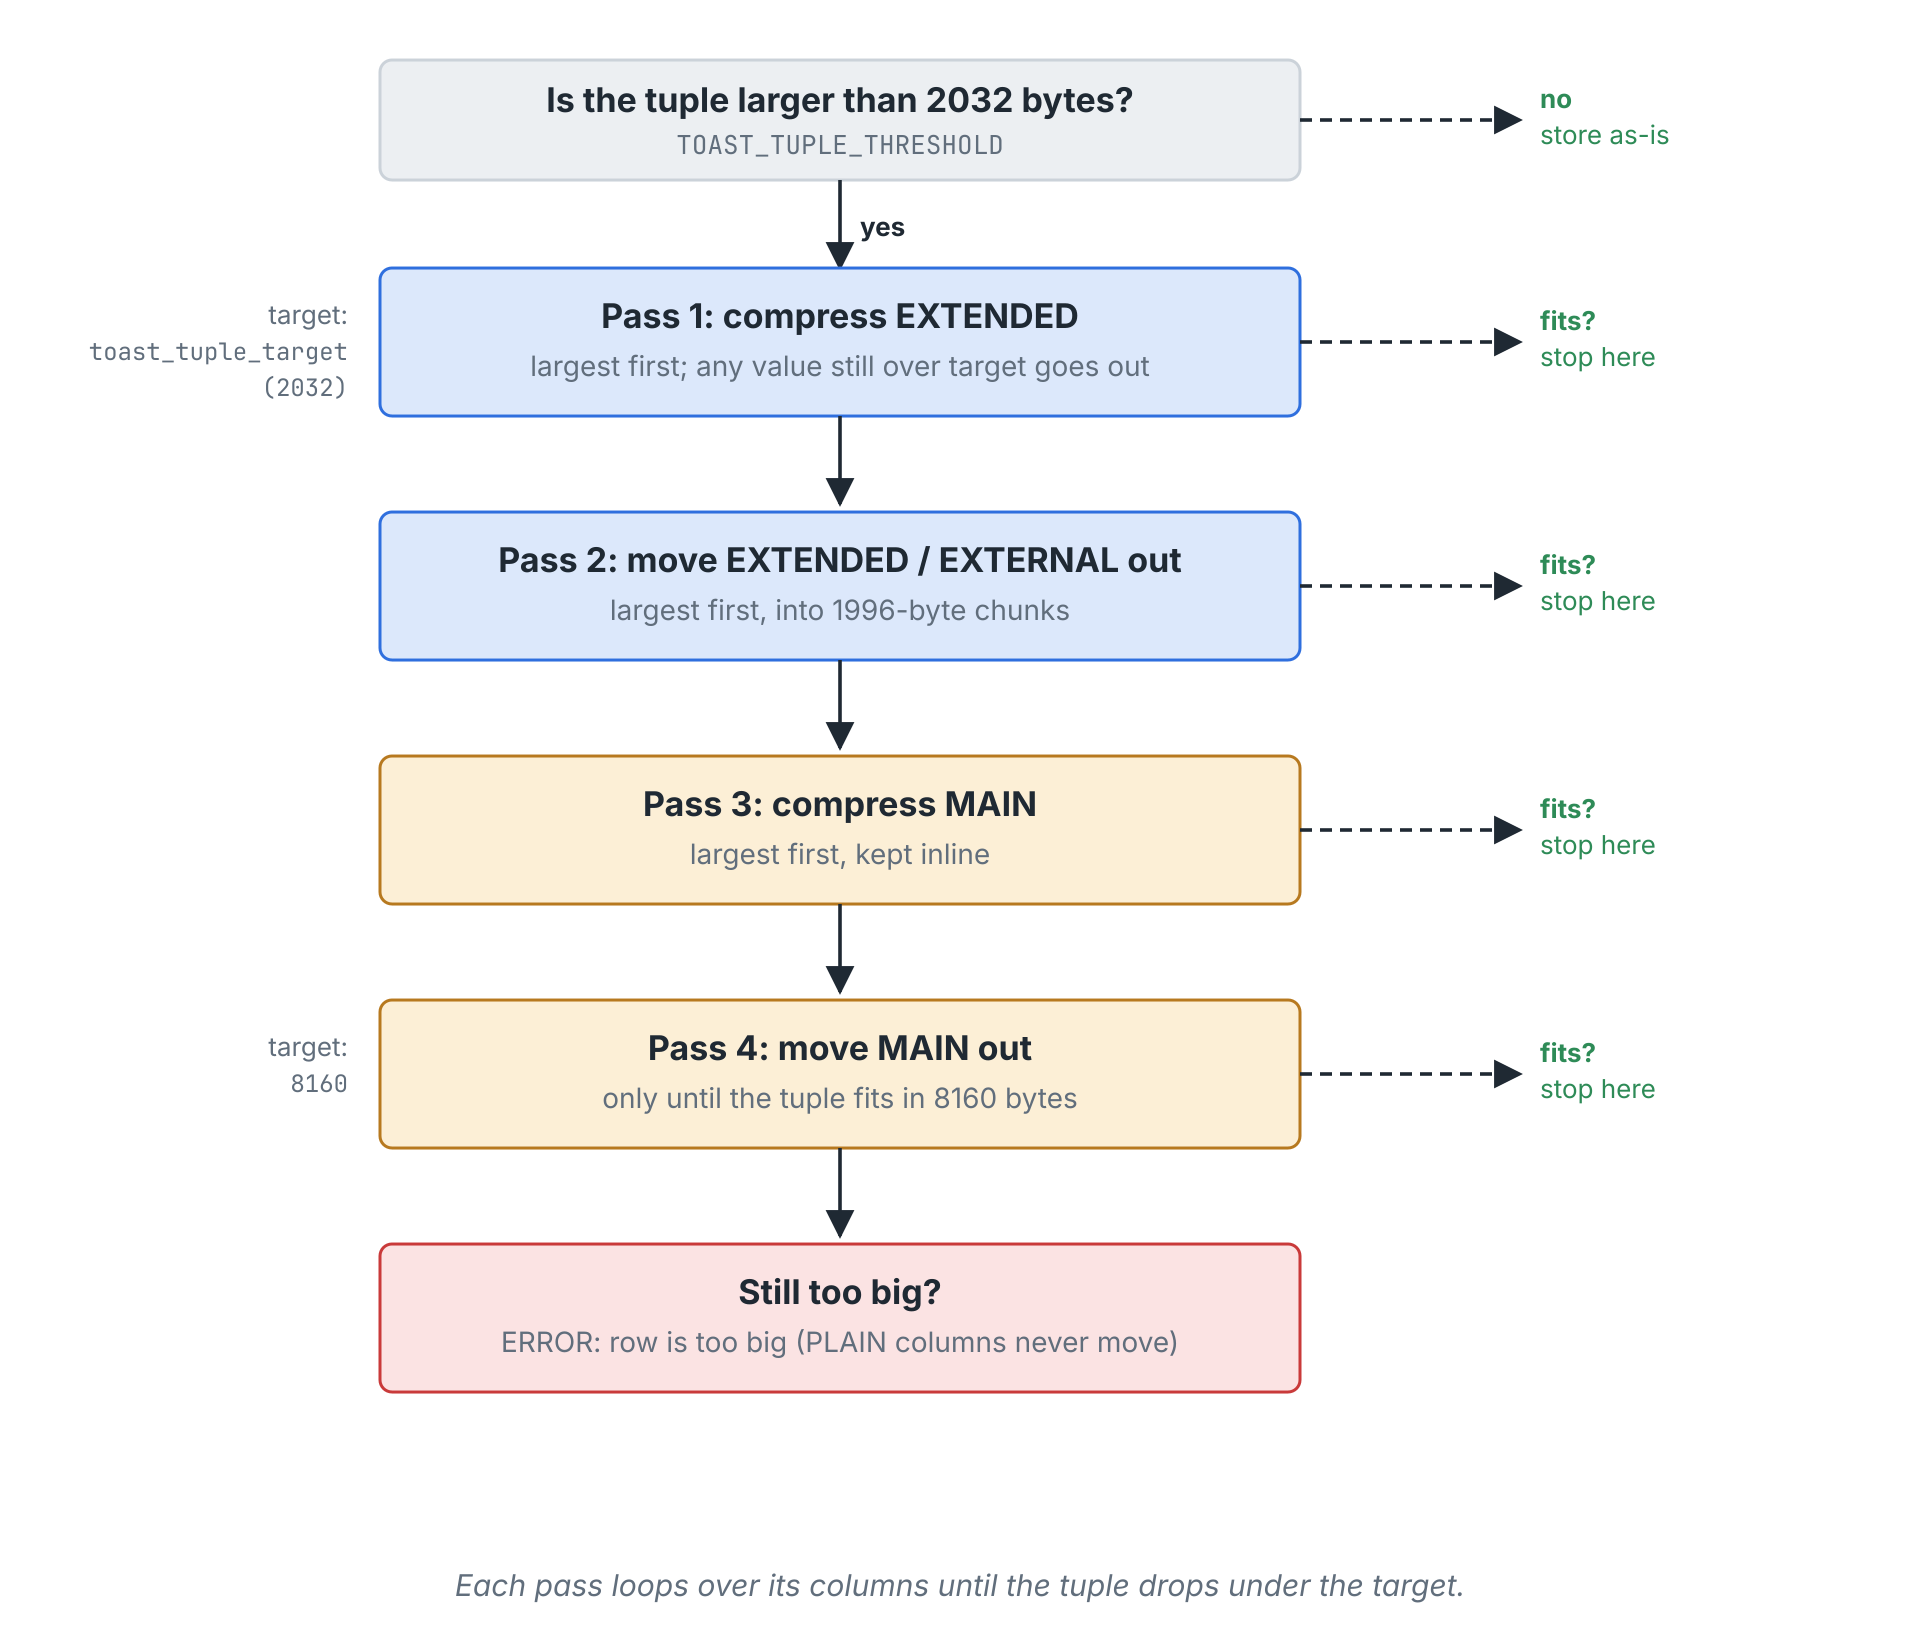
Being the default for JSON, all of our data follows the rules for EXTENDED. We can see it in action by checking a few rows:
SELECT ctid, event_id, length(event_data::TEXT) AS chars,
       pg_column_size(event_data) AS stored_bytes,
       pg_column_toast_chunk_id(event_data) AS toast_id
  FROM event_log
 WHERE event_id BETWEEN 335 AND 340
 ORDER BY event_id;

  ctid  | event_id | chars | stored_bytes | toast_id
--------+----------+-------+--------------+----------
 (57,2) |      335 |  5907 |         1981 |
 (57,3) |      336 |  5930 |         2004 |    16414
 (57,4) |      337 |  5942 |         1987 |    16415
 (57,5) |      338 |  5953 |         2005 |    16416
 (57,6) |      339 |  5978 |         1996 |    16417
 (57,7) |      340 |  5988 |         2034 |    16418
The toast_tuple_target storage setting tells Postgres when to toast column contents. The default is around 2KB of compressed data, and anything after that is moved into TOAST automatically. The example above has a row that compresses right under that limit, and as a result, never gets moved.
If we examine page 57 specifically, this becomes even more clear:
CREATE EXTENSION IF NOT EXISTS pageinspect;

SELECT lp, lp_len
  FROM heap_page_items(get_raw_page('event_log', 57))
 LIMIT 5;

 lp | lp_len
----+--------
  1 |   2022
  2 |   2029
  3 |     66
  4 |     66
  5 |     66
The tuple size of the rows that didn’t get toasted is much larger than those that did. That’s thanks to a pointer replacing the toasted values. And that’s not all. Toasted data is also broken into chunks. Every toasted value gets broken into 1996-byte blocks and stored in sequential order as rows in the toast table.
Now consider what this means for reads:
Any toasted value implies at least one fetch from the toast table. That’s a read on the toast index and a read on the toast table itself per chunk.
Chunks must be re-assembled. That’s extra memory usage and can be significant depending on chunk count.
Compressed data must also be decompressed. That’s both memory and CPU overhead.
The intuitive read of this is that TOAST is always worse. But is it?
Turning Up the Heat
Let’s run an experiment! We already have a table where some of the data is toasted. What happens if we force Postgres to select all of it?
This requires some setup. To begin, we create a non-toasted table by setting the event_data column to use MAIN storage. That allows it to be compressed, but not toasted unless the full tuple exceeds a Postgres page size. Like so:
CREATE TABLE non_toast (LIKE event_log INCLUDING INDEXES);
ALTER TABLE non_toast ALTER event_data SET STORAGE MAIN;
INSERT INTO non_toast SELECT * FROM event_log;
Then we can directly compare the costs of pulling out field 999 from the data:
EXPLAIN (ANALYZE, BUFFERS, COSTS OFF, SUMMARY OFF)
SELECT count(event_data->>'field_999') FROM event_log;

 Aggregate (actual time=6589.068..6589.070 rows=1.00 loops=1)
   Buffers: shared hit=246472 read=41655
   ->  Seq Scan on event_log (actual time=0.221..17.022 rows=100000.00 loops=1)
         Buffers: shared read=5969

EXPLAIN (ANALYZE, BUFFERS, COSTS OFF, SUMMARY OFF)
SELECT count(event_data->>'field_999') FROM non_toast;

 Aggregate (actual time=6166.877..6166.880 rows=1.00 loops=1)
   Buffers: shared read=40754
   ->  Seq Scan on non_toast (actual time=0.180..51.434 rows=100000.00 loops=1)
         Buffers: shared read=40754
Take a look at that! Shared buffers really saved our bacon on this one. Total buffer reads on the toasted column required 288127 total reads versus 40754 for the non-toasted version. Conversely, the toasted table is much smaller:
SELECT pg_size_pretty(pg_relation_size('event_log')) AS event_log,
       pg_size_pretty(pg_relation_size('non_toast')) AS non_toast;

 event_log | non_toast
-----------+-----------
 47 MB     | 318 MB
While Postgres can read through the heap faster, it then has to spend a lot of time seeking through the toast table. This size difference translates to some non-intuitive behavior. For instance, most interactions with the toasted table are actually much faster. Consider counting all rows:
EXPLAIN (ANALYZE, BUFFERS, COSTS OFF, SUMMARY OFF)
SELECT count(event_data) from event_log;

 Aggregate (actual time=26.397..26.398 rows=1.00 loops=1)
   Buffers: shared hit=282 read=5567
   ->  Seq Scan on event_log (actual time=0.369..13.726 rows=100000.00 loops=1)
         Buffers: shared hit=282 read=5567

EXPLAIN (ANALYZE, BUFFERS, COSTS OFF, SUMMARY OFF)
SELECT count(event_data) from non_toast;

 Aggregate (actual time=91.840..91.841 rows=1.00 loops=1)
   Buffers: shared hit=282 read=40670
   ->  Seq Scan on non_toast (actual time=0.303..74.908 rows=100000.00 loops=1)
         Buffers: shared hit=282 read=40670
That’s 26ms vs 91ms. Or jumping through offsets:
EXPLAIN (ANALYZE, BUFFERS, COSTS OFF, SUMMARY OFF)
SELECT * from event_log LIMIT 1 OFFSET 99999;

 Limit (actual time=16.579..16.581 rows=1.00 loops=1)
   Buffers: shared hit=377 read=5592
   ->  Seq Scan on event_log (actual time=0.215..12.908 rows=100000.00 loops=1)
         Buffers: shared hit=377 read=5592

EXPLAIN (ANALYZE, BUFFERS, COSTS OFF, SUMMARY OFF)
SELECT * from non_toast LIMIT 1 OFFSET 99999;

 Limit (actual time=53.276..53.277 rows=1.00 loops=1)
   Buffers: shared hit=188 read=40566
   ->  Seq Scan on non_toast (actual time=0.240..49.551 rows=100000.00 loops=1)
         Buffers: shared hit=188 read=40566
Now it’s 16ms vs 53ms. Or even updates:
\timing on

UPDATE event_log
   SET shares = shares + 1
 WHERE ticker = 'b53b';

Time: 62.412 ms

UPDATE non_toast
   SET shares = shares + 1
 WHERE ticker = 'b53b';

Time: 128.282 ms
Any time Postgres has to deal directly with the heap, performance suffers immensely. Toast pointers can act as an optimization, particularly when not interacting with the toasted column because they make each row on the heap much smaller.
This one kind of blew my mind. It turns out that the problem with the event_log table wasn’t necessarily the TOAST system, but the event_data column itself. It turns out there’s a way to fix that.
Achieving Golden Brown
Back then, “fixing that” meant to split the table. Our toy example is a mere 100k rows, but the real one was several million and the heap alone was over 1GB. Including TOAST on those huge XML blobs brought the total table size to over 20GB.
When an application is full of SELECT * and is repeatedly looking up and decoding toasted data, it can eventually take a toll. Even if we ignore the disk IO, that’s a lot of extra network bandwidth. “Just specify the column names!” you might say, and I agree. If only it were that easy to modify ORM-generated queries and five years of accumulated hand-written ones.
Here’s what the surgery looks like:
CREATE TABLE event_new
(
  event_id       BIGINT GENERATED BY DEFAULT AS IDENTITY PRIMARY KEY,
  ticker         VARCHAR(4) NOT NULL,
  strike         INT NOT NULL,
  shares         INT NOT NULL
  --- More columns went here
);

CREATE TABLE event_log_data
(
  event_id       BIGINT GENERATED BY DEFAULT AS IDENTITY PRIMARY KEY,
  event_data     JSON NOT NULL
);

INSERT INTO event_new (event_id, ticker, strike, shares)
SELECT event_id, ticker, strike, shares
  FROM event_log;

INSERT INTO event_log_data (event_id, event_data)
SELECT event_id, event_data
  FROM event_log;

ALTER TABLE event_log RENAME TO event_log_old;
ALTER TABLE event_new RENAME TO event_log;
What do we gain from this? For one, we no longer need to carry around the TOAST pointers in the main application table. Secondly, since this column was a mix of toasted and non-toasted values due to the toast_tuple_target cutoff, even non-toasted values have been relocated. We can see this in the new table heap sizes:
SELECT pg_size_pretty(pg_relation_size('event_log')) AS event_log,
       pg_size_pretty(pg_relation_size('event_log_data')) AS non_toast;

 event_log | non_toast
-----------+-----------
 5096 kB   | 46 MB
All operations will now be substantially faster simply because page density is now guaranteed to be higher. More rows fit on each page, and there are fewer pages required to represent the primary core of the table. The entire heap is now 5MB rather than 47MB, a saving of over 9x. If it’s at all possible to relocate large columns to an optional JOIN in a high-performance system, it may be worth taking a second look.
If you think we could have achieved a similar effect by setting toast_tuple_target arbitrarily low, think again. The TOAST system won’t even activate if a row value is shorter than TOAST_TUPLE_THRESHOLD, a compiled value that acts as a hard minimum. Values below this won’t even be considered for toasting. What can I say? Postgres is a picky eater.
The obvious objection is that applications now need a join. Well, the Postgres planner has you covered:
CREATE OR REPLACE VIEW event_log_all AS
SELECT e.*, d.event_data
  FROM event_log e
  LEFT JOIN event_log_data d USING (event_id);

EXPLAIN (ANALYZE, BUFFERS, COSTS OFF, SUMMARY OFF)
SELECT event_id, strike, shares
  FROM event_log_all WHERE event_id = 42;

 Index Scan using event_new_pkey on event_log e (actual time=0.032..0.034 rows=1.00 loops=1)
   Index Cond: (event_id = 42)
   Index Searches: 1
   Buffers: shared hit=3
The trick is the LEFT JOIN, making the event data optional even though we know every row has a value there. Queries that don’t specify the column will prune the JOIN and everyone is happy.
Crunchy Nirvana
As of Postgres 14, it’s even possible to choose the compression type. Stick with the venerable built-in pglz, or use lz4 if it’s been compiled into your binaries. The default for the entire server comes from default_toast_compression:
SHOW default_toast_compression;

 default_toast_compression
---------------------------
 pglz
Or it can be set using the COMPRESSION decorator during CREATE TABLE or ALTER TABLE.
One interesting note about the compression types is that pglz is somewhat quirky. It skips values under 32 bytes, demands at least 25% savings, and gives up entirely if it finds nothing to compress in the first 1KB. The last rule is kind of odd to see in action:
CREATE EXTENSION pgcrypto;

CREATE TABLE squeeze (method TEXT, payload TEXT);

ALTER TABLE squeeze ALTER payload SET COMPRESSION pglz;
INSERT INTO squeeze VALUES ('pglz', encode(gen_random_bytes(1024), 'base64') || repeat('Postgres! ', 1000));

ALTER TABLE squeeze ALTER payload SET COMPRESSION lz4;
INSERT INTO squeeze VALUES ('lz4', encode(gen_random_bytes(1024), 'base64') || repeat('Postgres! ', 1000));

SELECT method, length(payload) AS chars,
       pg_column_size(payload) AS stored,
       pg_column_compression(payload) AS compression,
       pg_column_toast_chunk_id(payload) AS toasted_chunk
  FROM squeeze;

 method | chars | stored | compression | toasted_chunk
--------+-------+--------+-------------+---------------
 pglz   | 11385 |  11385 |             |        415076
 lz4    | 11385 |   1517 | lz4         |
There are also some associated performance implications. Consider:
-- First test with pglz

TRUNCATE TABLE squeeze;

ALTER TABLE squeeze ALTER payload SET COMPRESSION pglz;

\timing on

INSERT INTO squeeze
SELECT 'pglz', repeat('Postgres!', 10000)
  FROM generate_series(1, 100000);

Time: 52179.203 ms (00:52.179)

SELECT sum(length(payload)) FROM squeeze;

    sum
------------
 9000000000

Time: 17108.284 ms (00:17.108)

-- Second test with lz4

TRUNCATE TABLE squeeze;

ALTER TABLE squeeze ALTER payload SET COMPRESSION lz4;

\timing on

INSERT INTO squeeze
SELECT 'lz4', repeat('Postgres!', 10000)
  FROM generate_series(1, 100000);

Time: 1774.048 ms (00:01.774)

SELECT sum(length(payload)) FROM squeeze;

    sum
------------
 9000000000
(1 row)

Time: 20929.714 ms (00:20.930)
When dealing with 100k rows of 10k compressed values, lz4 is a bit slower decompressing by about 20% in this case, but is over 30 times faster at compression. That’s absolutely staggering.
Final Thoughts
Look, we all want to play the blame game. I always blamed the TOAST system for how badly our application’s event_log table performed. Every time someone complained. Any occasion when a badly written query made it through the application and touched the table in a way that apparently enraged it and caused every page load to quadruple or time out entirely. In my head, TOAST was at fault.
Ironically, it was TOAST’s fault in a way, because it’s not aggressive enough. Think about it. Postgres needs TOAST_TUPLE_THRESHOLD to avoid activating the expensive machinery that deconstructs, compresses, and moves data to an external table. But imagine how things could look if anything could be offloaded arbitrarily. Unfortunately there’s no option for that. Out of PLAIN, MAIN, EXTENDED, and EXTERNAL, none cover the case for “move anything over 100 bytes and also compress it if it’s over 2k.” Though there’s an argument for using EXTERNAL on medium-sized but “large-ish” columns: we gain the benefit of a smaller heap, and data less than 1kb doesn’t tend to compress well anyway.
Instead, we have to compromise our schema design and introduce an extra join for parts of the application that actually interact with the bulky column. Views sidestep this to an extent, but it’s something of an ugly hack compared to leaving the table intact. We also can’t leverage this maneuver every single time a big column shows up, or our schema would end up a horrifying mess. Not all columns are “optional” enough to banish.
What TOAST provides is a suitable middle-ground. For the cost of a pointer, we get to essentially forget a huge block of text exists in the table at all. The heap is happier and we’re none the wiser. Compression speeds are also dramatically faster for those who switch to lz4.
So don’t be afraid of Postgres TOAST; it’s the best kind there is.